- Solve real problems with our hands-on interface
- Progress from basic puts and calls to advanced strategies
Interactive Options Course
Posted September 16, 2026 at 2:40 pm
Open Source Quantitative Finance
secfile is a package that provides simple and efficient access to the SEC’s EDGAR APIs (https://www.sec.gov/search-filings) for querying and retrieving filings.
The core functionality of the secfile package abstracts the complexities of interacting with SEC EDGAR APIs, such as session management, user agent declaration, rate limiting, index parsing, pagination of filing metadata, URL construction, document caching, and inline XBRL parsing. This abstraction allows users to focus on retrieving data rather than managing API details. Use cases include retrieving data across a range of workflows:
The package supports flexible query capabilities, including customizable form types, date ranges, and dimensions, and validates the retrieved data automatically. It handles the SEC’s fair access requirements, such as user agent declaration and rate limiting between requests, and caches downloaded documents for efficient retrieval of large datasets.
The implementation uses standard HTTP libraries to handle API interactions efficiently and supports both R and Python to make it accessible for a broad audience.
install.packages("secfile")# install.packages("pak")
pak::pak("jasonjfoster/file/r")library(secfile)
pip install secfile
pip install \
  git+https://github.com/jasonjfoster/file.git@main#subdirectory=python
import secfile as sec
Load the package and explore the available form types using secfile::data_forms in R or sec.data_forms in Python, and the available current report (“8-K”) item numbers using secfile::data_items in R or sec.data_items in Python:
| Workflows | Form types | Item numbers |
| Indexes | 10-K | 1.01 |
| Tenures | 10-Q | 1.05 |
| Submissions | 8-K | 2.02 |
| Facts | 8-A12B | 5.02 |
| ⋮ | ⋮ |
The SEC requires a user agent that declares contact information (e.g., “username@domain.com”) for fair access, so pass the user_agent argument to identify the user. Alternatively, pass session = get_session(user_agent) to reuse a connection across function calls.
The secfile::get_ciks function in R and sec.get_ciks function in Python get the Central Index Key (“CIK”) for one or more tickers from the SEC EDGAR APIs.
A data frame that contains the company, CIK, and ticker for each filer.
R
user_agent <- "username@domain.com"
ciks <- secfile::get_ciks(c("AAPL", "MSFT"), user_agent = user_agent)
Python
user_agent = "username@domain.com"
ciks = sec.get_ciks(["AAPL", "MSFT"], user_agent = user_agent)
The secfile::get_submissions function in R and sec.get_submissions function in Python get the filing metadata (“submissions”) from the SEC EDGAR APIs for one or more filers with optional form type and date range filters.
A data frame that contains the filing metadata for the specified filer(s) with the archives URL for each filing.
R
submissions <- secfile::get_submissions(ciks, forms = "10-K",
                                        from_date = "2023-01-01",
                                        user_agent = user_agent)
Python
submissions = sec.get_submissions(ciks, forms = "10-K",
                                  from_date = "2023-01-01",
user_agent = user_agent)The secfile::get_data function in R and sec.get_data function in Python get facts from inline XBRL filings from the SEC EDGAR APIs using the specified filing metadata. By default, the result contains all contexts that match the report date of each filing and includes the period type, start and end dates, and dimension axes and members for each context.
A data frame that contains facts from the SEC EDGAR APIs for the specified filing metadata with the period type, start and end dates, and dimension axes and members for each context.
R
data <- secfile::get_data(submissions, cache_dir = "cache",
                          user_agent = user_agent)
Python
data = sec.get_data(submissions, cache_dir = "cache",
user_agent = user_agent)Company-level totals are the contexts without dimensions (i.e., the rows where axis is empty). Balance-sheet facts are reported for a point in time, so filter the period_type column to “instant” contexts (duration contexts carry income-statement facts instead):
R
totals <- data[which((data[["axis"]] == "") &
                     (data[["period_type"]] == "instant")), ]
head(totals[ , c("cik", "report_date", "Assets",
                 "Liabilities", "StockholdersEquity", ...)])
Python
totals = data[(data["axis"] == "") & (data["period_type"] == "instant")]
totals[["cik", "report_date", "Assets",
"Liabilities", "StockholdersEquity", ...]].head()| cik | report date | assets (b) | liabilities (b) | equity (b) | ⋯ |
| 320193 | 2023-09-30 | 352.58 | 290.44 | 62.15 | ⋯ |
| 320193 | 2024-09-28 | 364.98 | 308.03 | 56.95 | ⋯ |
| 789019 | 2023-06-30 | 411.98 | 205.75 | 206.22 | ⋯ |
| 789019 | 2024-06-30 | 512.16 | 243.69 | 268.48 | ⋯ |
Each workflow defines the form types and date range, then follows the same steps to get the session and get the index, or to get the CIKs and get the submissions:
session <- secfile::get_session(user_agent)
index <- secfile::get_index(from_year = 2024, to_year = 2024,
forms = "10-K", session = session)index <- secfile::get_index(from_year = 2024,
forms = c("8-A12B", "25", "25-NSE"),
session = session)
tenures <- secfile::create_tenures(index, "8-A12B", c("25", "25-NSE"))Each workflow defines the form types and date range, then follows the same steps to get the session and get the index, or to get the CIKs and get the submissions:
session = sec.get_session(user_agent)
index = sec.get_index(from_year = 2024,
                      forms = ["8-A12B", "25", "25-NSE"],
                      session = session)
tenures = sec.create_tenures(index, "8-A12B", ["25", "25-NSE"])ciks = sec.get_ciks(["AAPL", "MSFT", "TSLA"], user_agent = user_agent)
submissions = sec.get_submissions(ciks, forms = "8-K",
from_date = "2026-01-01",
user_agent = user_agent)results = submissions[submissions["items"].str.contains("2.02", regex = False)]Next we use the secfile package to analyze how survivorship bias influences fundamental analysis of U.S. filers. A universe built from filers listed today ignores filers that were delisted along the way, so backtests inherit a selection bias toward survivors. To construct a point-in-time universe, we pair exchange listing registration (“8-A12B”) and removal (“25” and “25-NSE”) filings with the create_tenures function to determine listing status windows for each filer.
We focus on the cohort of filers that listed during 2020–2021, a period with a large share of initial public offerings and special-purpose acquisition companies, for three reasons. First, 2021 is the largest listing year in the sample, with roughly three times the listings of each of the 2016–2019 cohorts. Second, the 2020 and 2021 cohorts show the highest attrition within three years of listing (with 2022 close behind). Third, the cohort is the earliest observable over its entire life with inline XBRL, which phased in between 2019 and 2021. The table below reports listings and attrition by entry year. The delisted (%) column is cumulative as of June 30, 2026, and attrition horizons a cohort has not yet reached are marked “NA” (e.g., the three-year horizon for the 2023 cohort is incomplete until the end of 2026).
| entry year | listings | delisted (%) | ≤ 1y (%) | ≤ 2y (%) | ≤ 3y (%) |
| 2016 | 438 | 75 | 32 | 38 | 49 |
| 2017 | 506 | 71 | 26 | 37 | 45 |
| 2018 | 555 | 66 | 25 | 36 | 45 |
| 2019 | 539 | 67 | 29 | 42 | 48 |
| 2020 | 826 | 70 | 31 | 45 | 56 |
| 2021 | 1,497 | 68 | 15 | 36 | 53 |
| 2022 | 549 | 61 | 25 | 41 | 52 |
| 2023 | 454 | 49 | 33 | 42 | NA |
| 2024 | 816 | 26 | 19 | NA | NA |
| 2025 | 896 | 21 | NA | NA | NA |
For comparison, a tally by Jay Ritter at the University of Florida also peaks in 2021 (https://site.warrington.ufl.edu/ritter/ipo-data/). It reports 413 initial public offerings in 2020 and a record 924 in 2021, with special-purpose acquisition companies accounting for more than half of each year’s total. The tenure counts are higher because exchange listing registration also captures listings outside this tally, such as uplistings from over-the-counter markets, transfers between exchanges, spin-offs, and smaller offerings the tally excludes.
We then retrieve annual report (“10-K”) filings and extract company-level facts from the inline XBRL filings to compare a fundamental metric across two universes at each quarter-end. The metric is leverage, defined as total liabilities divided by total assets from the balance-sheet facts, and the universes are cohort filers listed at that time (“point-in-time”) and cohort filers still listed as of June 30, 2026 (“survivors”). Each universe uses each filer’s most recent annual report within the trailing year, so membership requires both an active tenure and a report in that window. Note that the analysis uses report dates for simplicity. This assumes the facts are available at the report date rather than at the later filing date, and the assumption applies to both universes. The objective is to measure the survivorship bias in the cross-sectional estimate:
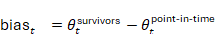
where is the cross-sectional median of the fundamental metric at time
. The point-in-time universe includes every cohort filer whose tenure contains time
, regardless of subsequent delisting, while the survivor universe conditions on tenures that remain active as of June 30, 2026.
At each date, the bias is the difference in medians, where leverage holds the cross-section of the metric, and survivors and point_in_time index the two universes at that date:
R
bias <- median(leverage[survivors]) - median(leverage[point_in_time])
Python
bias = leverage[survivors].median() - leverage[point_in_time].median()
The two universes draw on the same facts and differ only in membership, so the bias isolates the effect of conditioning on survival rather than differences in measurement. Note that the survivor universe is observable only in hindsight because membership conditions on tenures active as of June 30, 2026, while the point-in-time universe is available at each date.
After the tenures and facts are combined, we compare the cross-sectional estimates over time. The chart below shows the median leverage for the point-in-time and survivor universes. The analysis provides insight into how universe construction, specifically the inclusion or exclusion of delisted filers, affects conclusions drawn from fundamental data.

Data source: SEC EDGAR APIs: https://www.sec.gov/search-filings
The survivor universe shows a higher median than the point-in-time universe from December 2021 through December 2023: the difference opens at the 2021 cohort’s first annual reports and peaks at roughly 22 percentage points on September 30, 2022. The direction is the opposite of the classical expectation that distressed, highly levered filers delist: among the filers that exited, 64% had leverage below 10% at the peak, and median leverage was roughly 8% for exits versus 33% for survivors. The exits were therefore predominantly shells rather than distressed operators. In the tally above, a large share were special-purpose acquisition companies, which hold trust assets with minimal liabilities. These companies typically have about two years, plus extensions, to complete an acquisition before liquidating, a deadline that concentrated the 2021 cohort’s attrition in the second and third years after listing. The two universes converge by construction once delisted filers no longer report within the trailing year. In this cohort, conditioning on surviving filers overstates the cross-sectional median because the filers that later exited had lower leverage than the survivors. The concentration of the 2021 cohort’s exits in the second and third years after listing determines how large the bias becomes and how long it persists. More generally, the sign of the bias depends on where the filers that later exit sit in the leverage distribution relative to survivors.
The secfile package provides simple and efficient access to the SEC’s EDGAR APIs for querying and retrieving filings. It abstracts the complexities of session management, user agent declaration, rate limiting, index parsing, pagination of filing metadata, URL construction, document caching, and inline XBRL parsing. This allows users to focus on retrieving data across a range of workflows, including indexes, tenures, submissions, and facts. The package supports flexible query capabilities, such as customizable form types, date ranges, and dimensions, and handles the SEC’s fair access requirements automatically while caching downloaded documents to retrieve large datasets efficiently. It is available for both R and Python to make it accessible for a broad audience. The analysis of survivorship bias illustrates how the package can be used to construct point-in-time universes and interpret differences in fundamental estimates across universes. The workflow is available in both languages: for more examples, go to https://github.com/jasonjfoster/file/tree/main/r/examples for R code and https://github.com/jasonjfoster/file/tree/main/python/examples for Python code.
Information posted on IBKR Campus that is provided by third-parties does NOT constitute a recommendation that you should contract for the services of that third party. Third-party participants who contribute to IBKR Campus are independent of Interactive Brokers and Interactive Brokers does not make any representations or warranties concerning the services offered, their past or future performance, or the accuracy of the information provided by the third party. Past performance is no guarantee of future results.
This material is from Jason Foster and is being posted with its permission. The views expressed in this material are solely those of the author and/or Jason Foster and Interactive Brokers is not endorsing or recommending any investment or trading discussed in the material. This material is not and should not be construed as an offer to buy or sell any security. It should not be construed as research or investment advice or a recommendation to buy, sell or hold any security or commodity. This material does not and is not intended to take into account the particular financial conditions, investment objectives or requirements of individual customers. Before acting on this material, you should consider whether it is suitable for your particular circumstances and, as necessary, seek professional advice.
The third-party code discussed within this article is not investment or trading advice, and is for proof-of-concept, educational, and illustrative purposes only. IBKR makes no representations or warranty regarding its accuracy or completeness. Users are solely responsible for conducting their own independent testing and due diligence before applying any code or concepts in a live or production environment
Please keep in mind that the examples discussed in this material are purely for technical demonstration purposes, and do not constitute trading advice. Also, it is important to remember that placing trades in a paper account is recommended before any live trading.
Alternative investments can be highly illiquid, are speculative and may not be suitable for all investors. Investing in Alternative investments is only intended for experienced and sophisticated investors who have a high risk tolerance. Investors should carefully review and consider potential risks before investing. Significant risks may include but are not limited to the loss of all or a portion of an investment due to leverage; lack of liquidity; volatility of returns; restrictions on transferring of interests in a fund; lower diversification; complex tax structures; reduced regulation and higher fees.
IPO investments carry substantial risks including extreme price volatility, limited operating history, lack of liquidity, potential for significant losses, and uncertainty regarding future performance.
Investing in Special Purpose Acquisition Companies (SPACs) involves significant risks. As these companies typically have no operating history, their value depends largely on the success of future acquisitions, which may be uncertain. Investors should carefully consider potential volatility, dilution, and the management team’s track record before investing.
An investment in an OTC security is speculative and involves a high degree of risk. Many OTC securities are relatively illiquid, or "thinly traded," which tends to increase price volatility. Illiquid securities are often difficult for investors to buy or sell without dramatically affecting the quoted price. In some cases, the liquidation of a position in an OTC security may not be possible within a reasonable period of time.


Join The Conversation
For specific platform feedback and suggestions, please submit it directly to our team using these instructions.
If you have an account-specific question or concern, please reach out to Client Services.
We encourage you to look through our FAQs before posting. Your question may already be covered!